
Every machine learning model that predicts, classifies, or generates something first has to see examples of what a correct answer looks like. Data labeling is how those examples get made. Skip it, or do it inconsistently, and the model has nothing reliable to learn from.
Most teams do not think about labeling until the model is already underperforming. By then, the fix is not a better algorithm. It is going back to the data and asking who labeled it, how, and whether anyone checked.
What Data Labeling Means, in Plain Terms
Data labeling means tagging raw data, an image, a sentence, an audio clip, so a model can recognize a pattern in it. A model shown a thousand photos with no labels learns nothing. Shown the same thousand photos with a box drawn around every car in them, it starts learning what a car looks like.
The same idea applies across formats: sentiment tags on customer messages, transcriptions on audio, boxes and outlines on images and video. The technique changes by data type. The underlying job does not: turning something a person already understands into something a model can learn from.
Before any of that tagging starts, most raw data needs to be cleaned, deduplicated, and structured, a step usually handled through data processing work rather than labeling itself.
The full range of what can be labeled, images, video, text, audio, and structured documents, along with the formats each one typically needs to land in, such as COCO, YOLO, or plain JSON, is broad enough to fill its own guide. Our data annotation services page breaks each type down in more detail.
Why This Step Decides Whether Your AI Project Works
Was the training set reviewed by more than one person?
Did every annotator apply the same standard to the same edge case?
Is there a record of which examples were rejected, and why?
Did anyone confirm that the test set and the training set were labeled by the same rules?
Most teams cannot answer these questions until the model is already underperforming.
Inconsistent labeling rarely shows up as an obvious error. It shows up as a model that scores well in testing and performs poorly in production, because the people who built the test set and the people who built the training set did not apply the same rules.
That gap is expensive to find late.
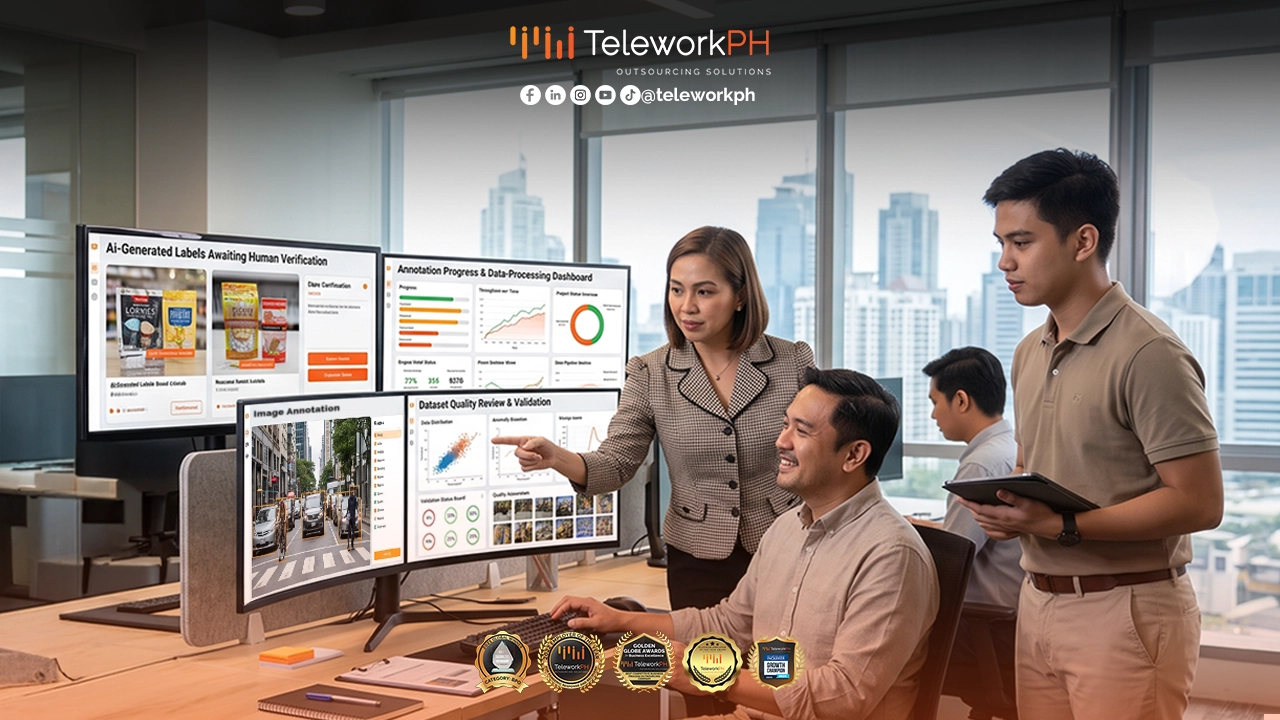
There is a name for the measurement that catches this early: inter-annotator agreement, the rate at which two independent reviewers label the same item the same way. A project with a plan for tracking it catches drift before it reaches production. A project without one usually finds out from a customer instead.
The judgment calls annotators make on ambiguous examples are exactly the kind of human input AI systems still cannot replace.
A Simple Way to Tell If Your Project Needs It
Not every AI project needs a labeling workflow. A system built on fixed rules, if a customer’s order total exceeds a set amount, flag it for review, needs no examples at all. A system that has to recognize a pattern a person cannot fully write down as a rule does.
A quick way to tell which one describes your project. Ask:
- Does the model predict, classify, or generate something, rather than follow a fixed set of instructions?
- Do you already have examples of correct answers, or would someone need to create them?
- Is a person currently doing this task by judgment, in a way that would be hard to reduce to a flowchart?
A yes to any of these usually means the project runs on labeled data somewhere in its pipeline, whether that data exists yet or not.
When to Start Planning for It
Labeling gets treated as a late-stage task more often than it should. Teams pick a model architecture, write the training loop, and only then ask where the training data is coming from.
By then, the timeline is already tight.
A pilot batch, a small sample reviewed before full production starts, is meant to catch labeling problems while the cost of fixing them is still small. Planning for that step at the same time as choosing a model architecture, rather than after, is what keeps a training start date from slipping.
A team that already has annotators trained and ready can typically be fully staffed within five to seven business days of a signed agreement. A team built from scratch cannot move that fast, which is the real argument for planning early rather than a sales pitch for any particular vendor.
Build a Small Internal Team, or Bring in Outside Help?
Some businesses keep this in-house, especially early on, when the dataset is small and only a few people understand the edge cases well enough to label them consistently. That approach protects context that would take a new team time to learn.
Most switch once labeling stops being a one-time task and becomes a recurring one: a model that needs monthly retraining, a product that keeps generating new edge cases, a dataset large enough that in-house staff get pulled off their actual jobs to keep up.
That second pattern is the more common one.
The idea that outsourced labeling automatically means lower quality is not accurate. It is a reflection of the QA structure wrapped around the team, not the location of the team.
Evaluating a specific labeling partner, their QA process, security setup, supported tools, and pilot approach, is a separate decision from recognizing that a labeling workflow is coming. That comparison deserves its own look once the first decision is made.
What This Costs to Get Right
Cost is usually the first question and the hardest one to get a straight answer to. The ranges below reflect how businesses typically staff a dedicated offshore annotation team. They are not a per-label quote, since that number depends on task complexity and volume.
| Engagement Model | Typical Cost | Best Fit |
|---|---|---|
| Full BPO partnership | $1,800–$2,500 per person, per month, all-in | Ongoing or high-volume labeling work |
| Employer of Record (EOR) | $400–$800 per month, plus salary | Hiring a specific annotator or team lead directly |
| Building an owned entity | $15,000–$30,000 to set up | Large, long-term operations only |
Onboarding, tooling setup, and process documentation typically add $2,000 to $5,000 per person before a team is fully productive. Most businesses see a payback period of one to three months compared with hiring the equivalent role in the United States, where the same work typically costs 50 to 60 percent more to run in-house.
How Telework PH Fits Into This
At Telework PH, we have spent over ten years building offshore teams, including dedicated data annotation teams, for companies that could not afford to get the labeling step wrong. More than 1,600 trained annotators have supported over 200 AI and technology clients on a process built around task-level review, team-lead audit, and manager sign-off before anything ships, with NDAs and restricted-access workflows standard on every engagement.
If the checklist above points toward outsourcing, our data annotation services page covers how a project moves from a pilot batch to a fully staffed team.
FAQ
Does every AI project need labeled data?
No. A system built on fixed, explicit rules does not need examples to learn from. A system that has to recognize a pattern a person currently judges by eye or ear, rather than a rule someone can write down, usually does.
What happens if training data is labeled inconsistently?
The model learns inconsistent patterns. This often does not show up during testing. It shows up later, in production, when the model behaves unpredictably on cases that resemble the training data closely enough to have been labeled the same way, but were not.
Can data labeling be automated instead of done by humans?
Some of it can, through pre-labeling tools that suggest a tag for a person to confirm or correct. Fully automated labeling with no human review tends to reintroduce the same inconsistency problem it is meant to solve, since the tool making the suggestions has its own blind spots.
When in a project timeline should labeling start?
At the same time the model architecture is chosen, not after. A pilot batch reviewed early catches labeling problems while they are still cheap to fix, rather than after a full dataset has already been built the same inconsistent way.
Is data labeling a one-time task or an ongoing one?
It depends on the project. A single, fixed dataset might only need labeling once. A model that retrains regularly, or a product that keeps generating new edge cases, turns labeling into a recurring part of the workflow.
How much does it typically cost to build a labeling function?
A dedicated offshore annotation team built through a full BPO partnership typically runs $1,800 to $2,500 per person, per month, all-in. Onboarding and process setup usually adds $2,000 to $5,000 per person up front.
Should a business label data in-house or outsource it?
In-house tends to work for a single, highly specialized dataset that only a few internal people understand well enough to label correctly. Outsourcing tends to make more sense once labeling becomes a recurring cost rather than a one-time task.
One Thing to Check Before Your Next Retrain
Pull twenty random labeled examples from the current training set and hand them to two different reviewers without telling them the original label. Count how many they disagree on.
That number is the real state of the dataset. It matters more than the accuracy score from the last training run.
Ready to Find Out What Your AI Project Actually Needs?
A model that keeps missing in production usually does not have a modeling problem. It has a labeling problem no one measured. Human judgment is still the part of an AI system that raw compute cannot replace, and it starts with the people labeling the data a model learns from.
At Telework PH, we help AI teams figure out whether a labeling workflow belongs in-house or with a dedicated offshore team, then staff and run it either way. Book a free strategy call to walk through your dataset, your timeline, and what a pilot batch would look like for your project.